Overview
Iterate smarter, not more
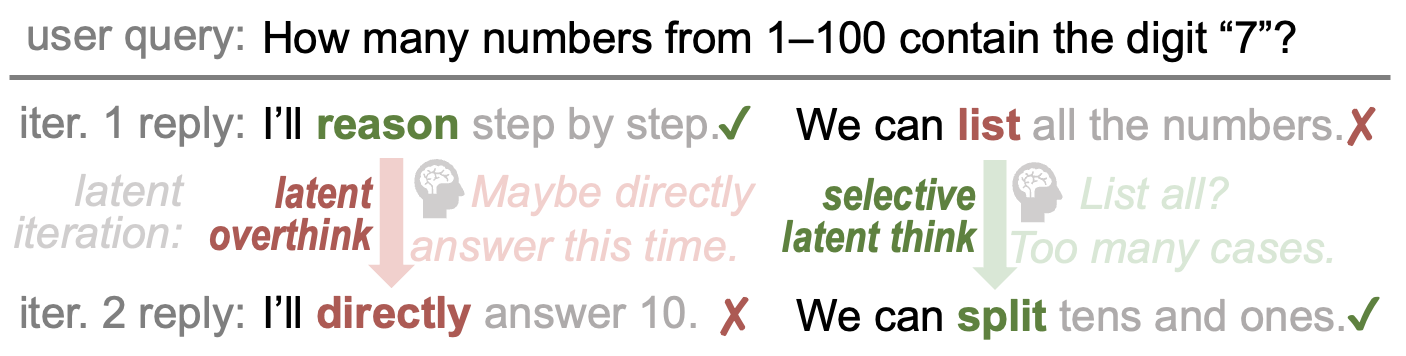
Looped transformers refine token predictions through multiple latent iterations — but iterating on every token wastes compute and risks latent overthinking, where correct predictions get flipped to errors.
The Discovery
Most tokens don't need to think twice.
We identify latent overthinking — where extra iterations hurt rather than help — and show that selective iteration unlocks significant untapped potential.
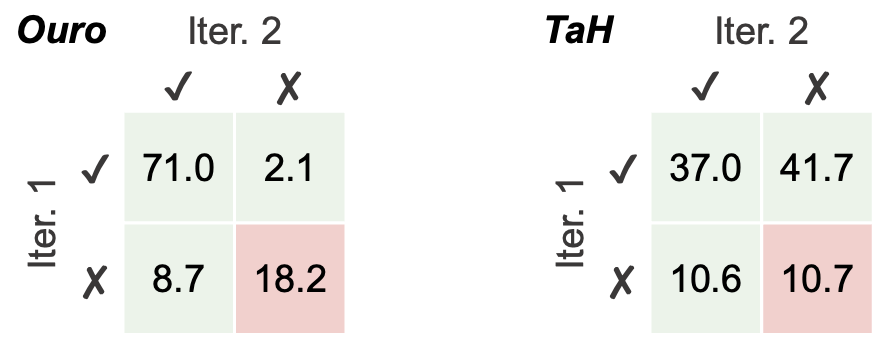
Because Ouro trains all iterations to predict all tokens, predictable tokens across depths largely overlap, leaving more tokens unpredictable by any iteration. TaH instead specializes deeper iterations for hard tokens, reducing overlap and improving coverage under selective iteration.
Architecture
TaH Design
Three architectural innovations enable efficient selective latent iteration.
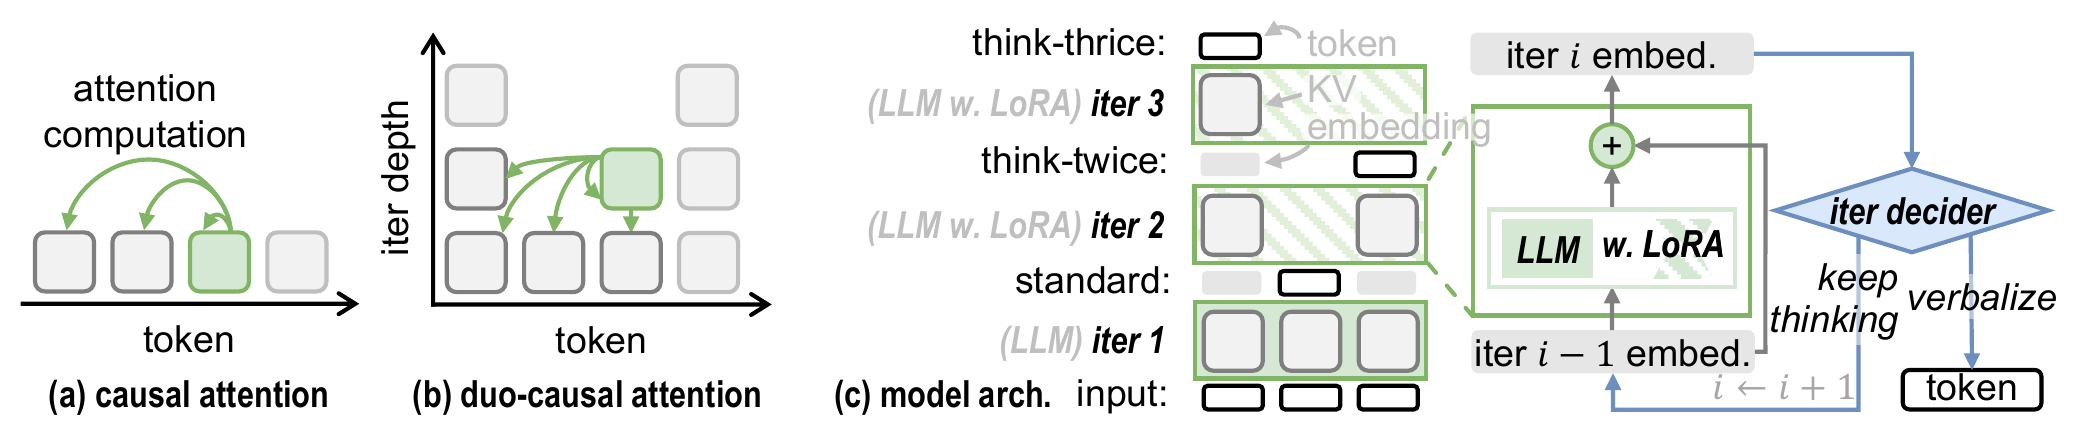
TaH Overview. (a) Regular causal attention. (b) Duo-causal attention extends causality to two dimensions. (c) TaH selectively iterates or verbalizes tokens using LoRA adapters and a neural iteration decider.
Duo-Causal Attention
2D causality across token positions and iteration depths — compatible with FlashAttention, no custom CUDA kernels needed
Depth-aware LoRA
LoRA adapters at $d > 1$ shift the objective from next-token prediction to hard-token refinement with <3% extra parameters
Neural Iteration Decider
Lightweight MLP that predicts which tokens need deeper thinking — trained to imitate the oracle policy in a stable two-stage scheme
Standard Forward Pass (Depth 1)
Token embeddings enter the LLM backbone for a standard forward pass at depth $d=1$. The model uses its original pretrained weights $\theta$ without any LoRA adaptation. This first iteration produces standard next-token predictions. The decider then selects tokens for further refinement.
Duo-Causal Attention
Unlike standard causal attention (1D: attend to previous positions), duo-causal attention extends causality to two dimensions: tokens attend to both previous positions and shallower iteration depths. Formally: $X_{\le i}^{(\le d)} = \{x_j^{(k)} \mid j \le i, k \le d\}$.
Depth Adapter (LoRA)
At deeper iterations ($d > 1$), LoRA adapters activate on top of the shared backbone: $\theta_d = \theta + \Delta$. This shifts the model's objective from general next-token prediction to focused hard-token refinement. Residual connections across iterations simplify the refinement process.
Neural Iteration Decider
A lightweight MLP ($\mathcal{I}_\phi$) reads concatenated hidden states from shallow, middle, and final LLM layers to predict a continuation probability $\hat{c}_i^{(d)} \in [0,1]$. If $\hat{c}_i^{(d)} < c_{\text{threshold}}$, the token verbalizes; otherwise it continues to the next iteration depth.
Two-stage training scheme
The backbone LLM and iteration decider are tightly coupled — joint training is unstable. We decouple them with a two-stage approach under a fixed oracle policy $\pi$:
Stage 1: Backbone Training
Fine-tune the LLM ($\theta$) and LoRA ($\Delta$) with $\pi$-guided iteration. Loss = standard next-token prediction at the oracle-determined depth. This preserves first-iteration accuracy for easy tokens while training deeper iterations to refine hard ones.
Stage 2: Decider Training
Freeze the backbone and train the decider ($\phi$) to imitate $\pi$'s continuation decisions via weighted binary cross-entropy. Class weights handle the imbalance between continue and stop labels.
Experiments
Benchmark Results
Results across nine reasoning benchmarks at three model scales. TaH matches the baseline parameter count by removing one backbone layer; TaH+ retains the full backbone and adds less than 3% parameters. Accuracy gains below compare TaH+ with Standard.
| Method | AIME25 | Olympiad | AMC23 | MATH500 | GSM8K | GPQA | MMLU | HE++ | MBPP++ | Average |
|---|---|---|---|---|---|---|---|---|---|---|
| Standard | 1.9 | 15.4 | 22.7 | 39.9 | 58.2 | 31.1 | 54.2 | 16.8 | 28.8 | 29.9 |
| SoftThink | 2.9 | 14.0 | 22.2 | 39.6 | 55.9 | 24.7 | 53.0 | 14.3 | 29.5 | 28.5 |
| Ouro | 2.1 | 14.2 | 19.7 | 37.4 | 56.6 | 35.4 | 54.0 | 18.9 | 23.5 | 29.1 |
| AlwaysThink | 1.3 | 12.6 | 21.9 | 37.8 | 52.6 | 30.8 | 51.4 | 9.1 | 13.8 | 25.7 |
| TaH | 2.1 | 19.1 | 24.1 | 46.2 | 63.6 | 29.0 | 56.4 | 21.6 | 33.9 | 32.9 |
| TaH+ | 4.6 | 20.6 | 24.7 | 51.8 | 67.6 | 31.3 | 59.0 | 22.0 | 35.1 | 35.2 |
Real-world efficiency on A800 GPU
1.7B model, AIME25, 8K max token length on a single NVIDIA A800 GPU:
| Standard | AlwaysThink | TaH | |
|---|---|---|---|
| Avg. Depth | 1.00 | 2.00 | 1.06 |
| Memory (GB) | 4.3 | 6.8 | 4.6 |
| Latency (s) | 210.6 | 747.2 | 301.4 |
| Throughput (tok/s) | 38.9 | 11.0 | 27.2 |
TaH iterates twice on only 6% of tokens. Compared with AlwaysThink, it uses 32% less memory and has a 2.48× decoding speedup in this setting. Standard remains faster.
Contributions
Key Contributions
Selective Latent Iteration
We identify latent overthinking in looped transformers and use selective iteration to concentrate computation on hard tokens.
Specialized Architecture
Duo-causal attention, depth-aware LoRA, and neural iteration decider — three components that natively support selective iteration with full training parallelism.
Efficient & Effective
TaH+ improves average accuracy over Standard by 5.3–6.2 percentage points at 0.6B and 1.7B, with less than 3% extra parameters. TaH averages 1.07 iterations, skipping extra computation for 93% of tokens.
Citation
Cite our work.
If you find TaH useful for your research, please consider citing our paper.
@inproceedings{fu2026think,
  title={Think-at-Hard: Dynamic Looped Transformers for Improved Reasoning},
  author={Fu, Tianyu and You, Yichen and Chen, Zekai and Dai, Guohao and Yang, Huazhong and Wang, Yu},
  booktitle={Proceedings of the 43rd International Conference on Machine Learning (ICML 2026)},
  series={Proceedings of Machine Learning Research},
  volume={306},
  address={Seoul, South Korea},
  note={Best Paper Shortlist, ICLR 2025 LIT Workshop},
  year={2026}
}