Q: Which animal hit the cat? Answer it simply.
Combining similarity and importance for video token reduction on large vision-language models.
Core Idea
Importance answers which tokens matter. Similarity answers which of those tokens are redundant. FrameFusion uses both signals instead of treating pruning as the only compression tool.
Unimportant
Tokens with low cumulative attention are removed under the compute budget.
Important + Similar
Redundant adjacent-frame tokens are averaged, preserving visual meaning while reducing length.
Important + Unique
Distinct tokens survive to carry scene details, temporal events, and task-relevant evidence.
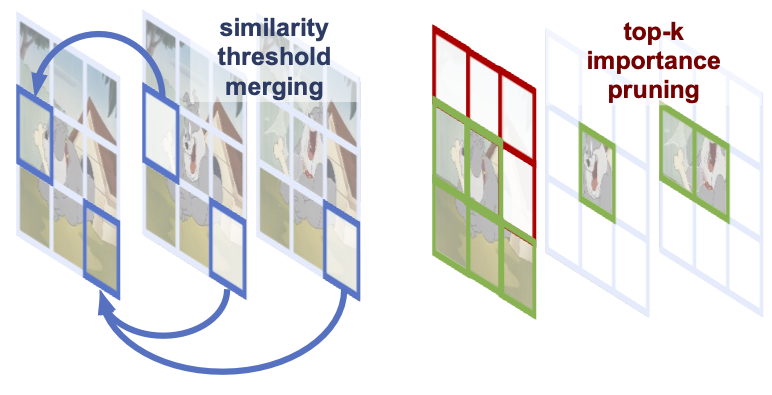
FrameFusion first merges tokens with similarities above a threshold at shallow layers, then applies top-k importance pruning to meet the target token budget.
Corresponding visual tokens from adjacent frames are compared with cosine similarity. Highly similar tokens are grouped and averaged across successive shallow layers.
After redundant tokens are fused, FrameFusion uses cumulative attention scores to retain the most important remaining tokens within the compute budget.
Tokens are permanently reduced for later layers, so both attention and feed-forward computation become cheaper as inference proceeds.
Observations
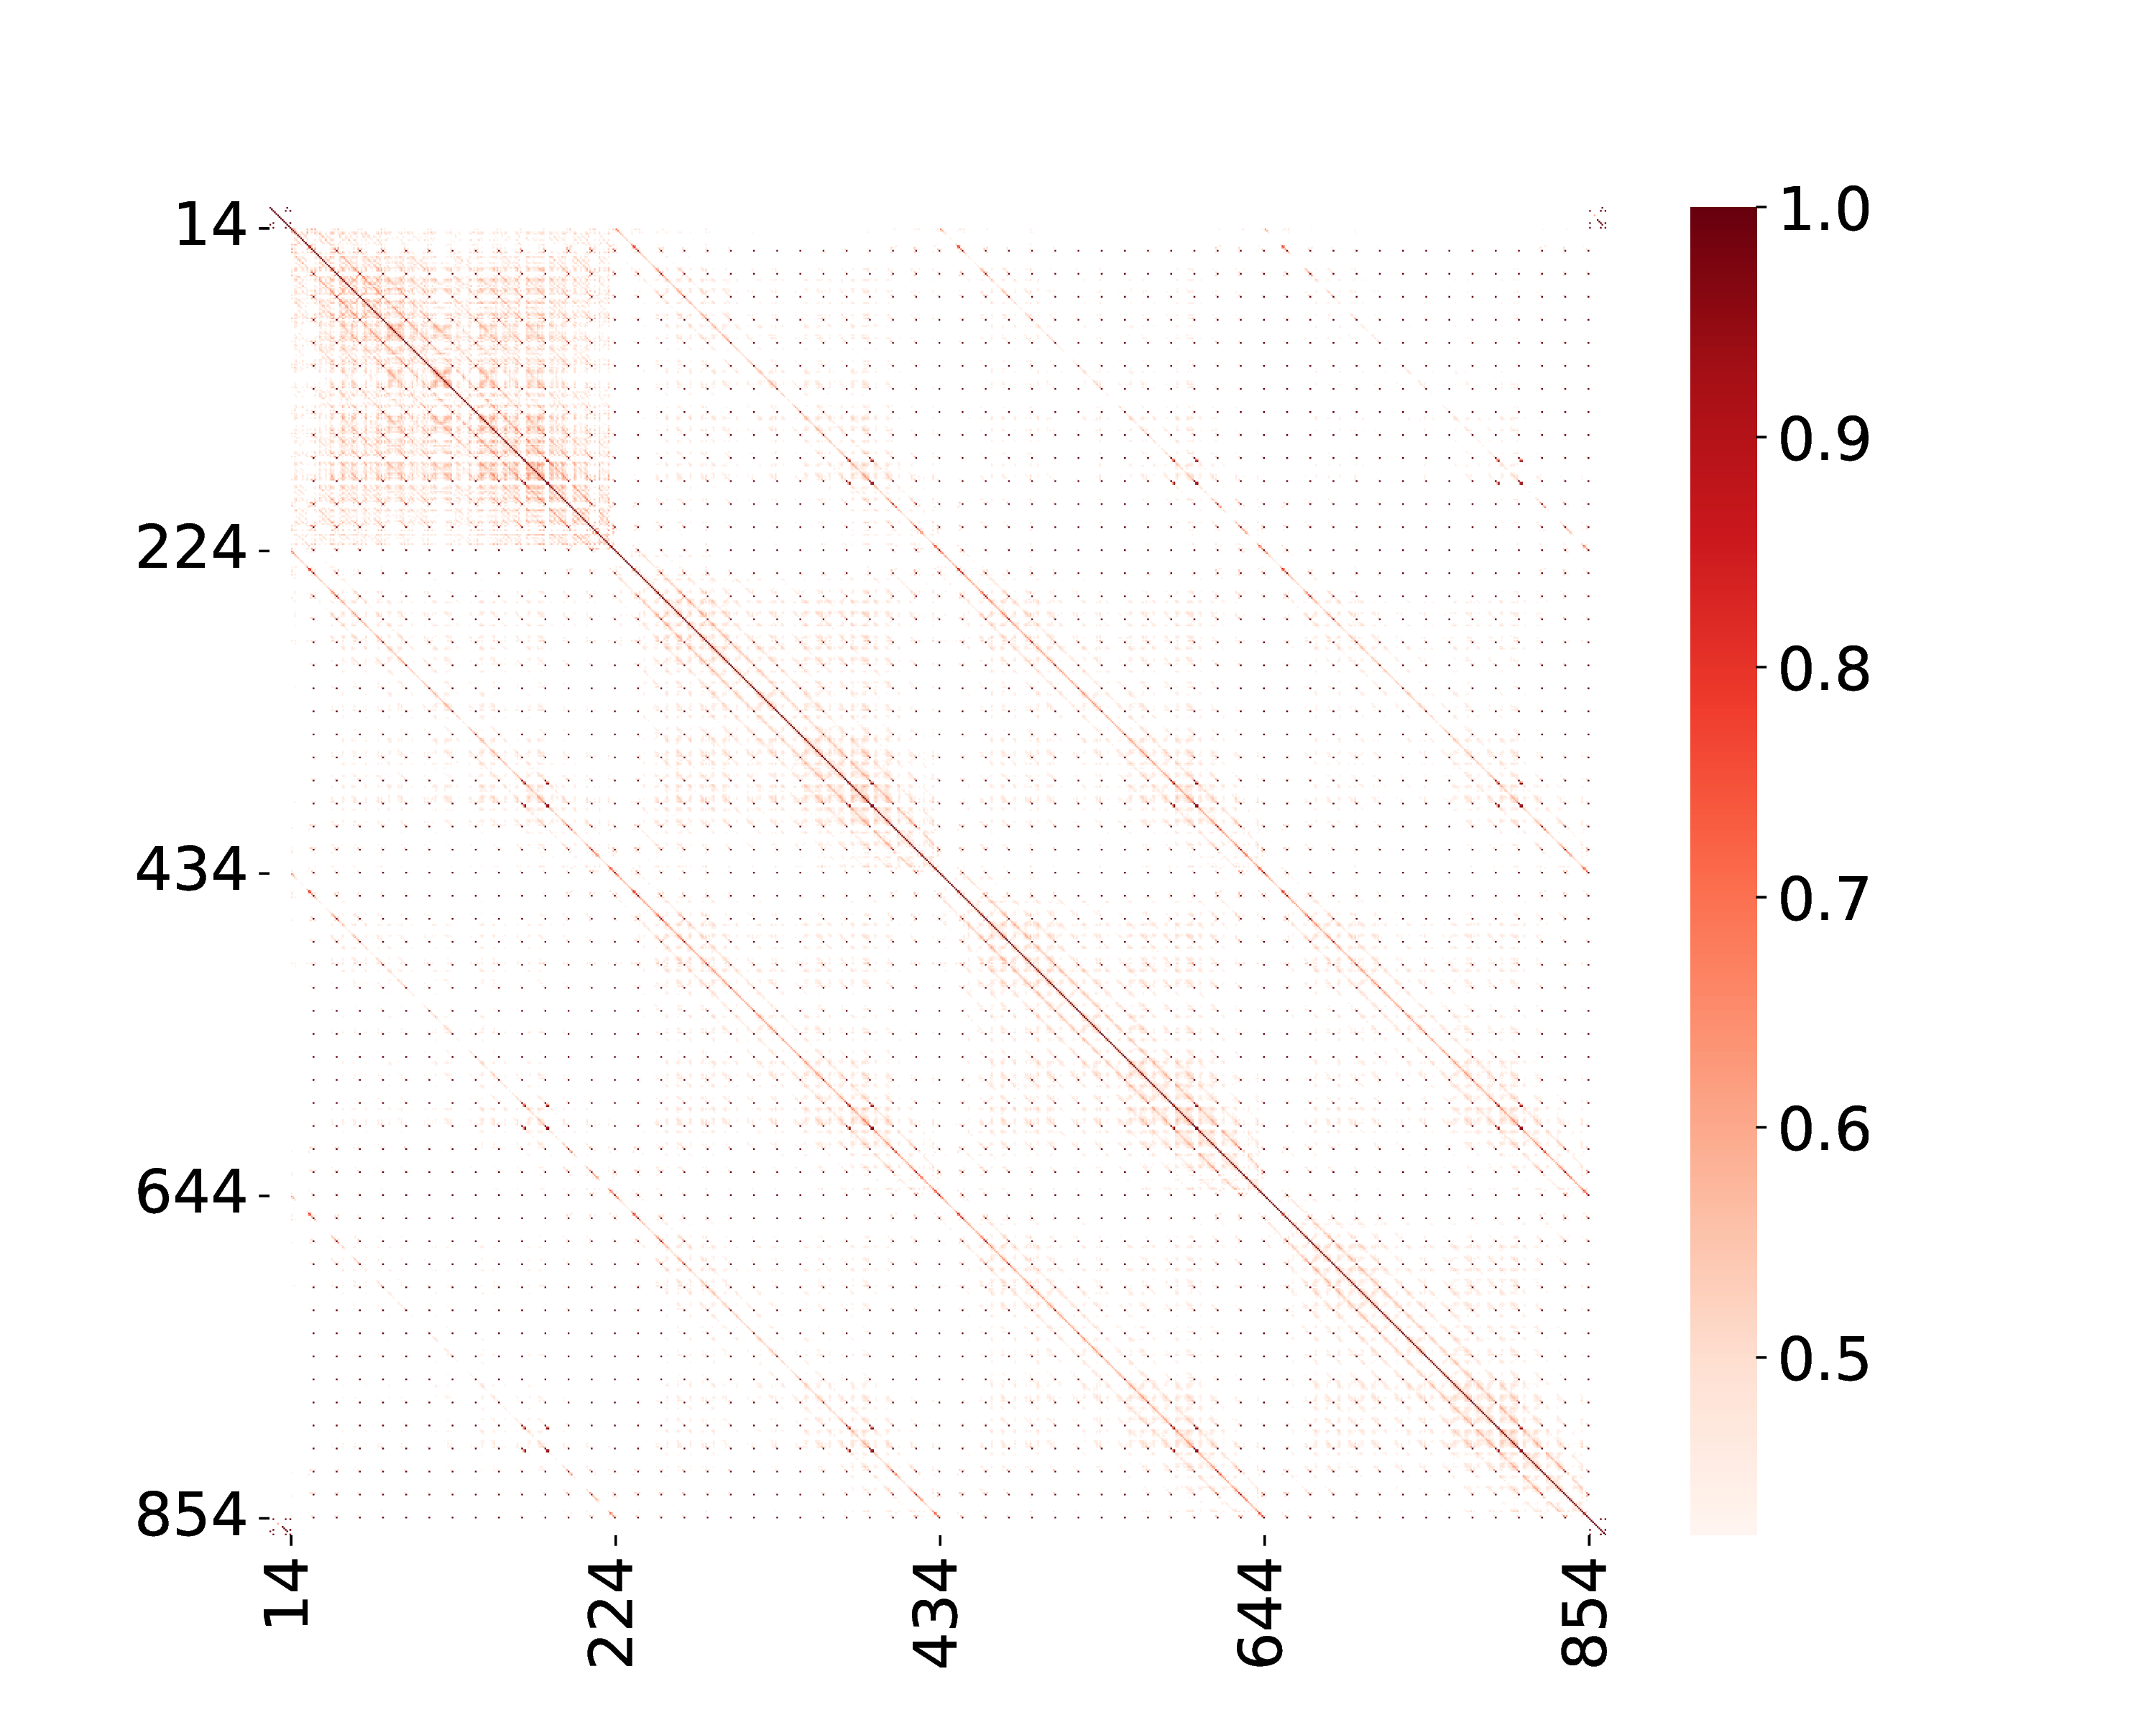
High similarity between adjacent frames
Design Choice: O(N) adjacent-only computation
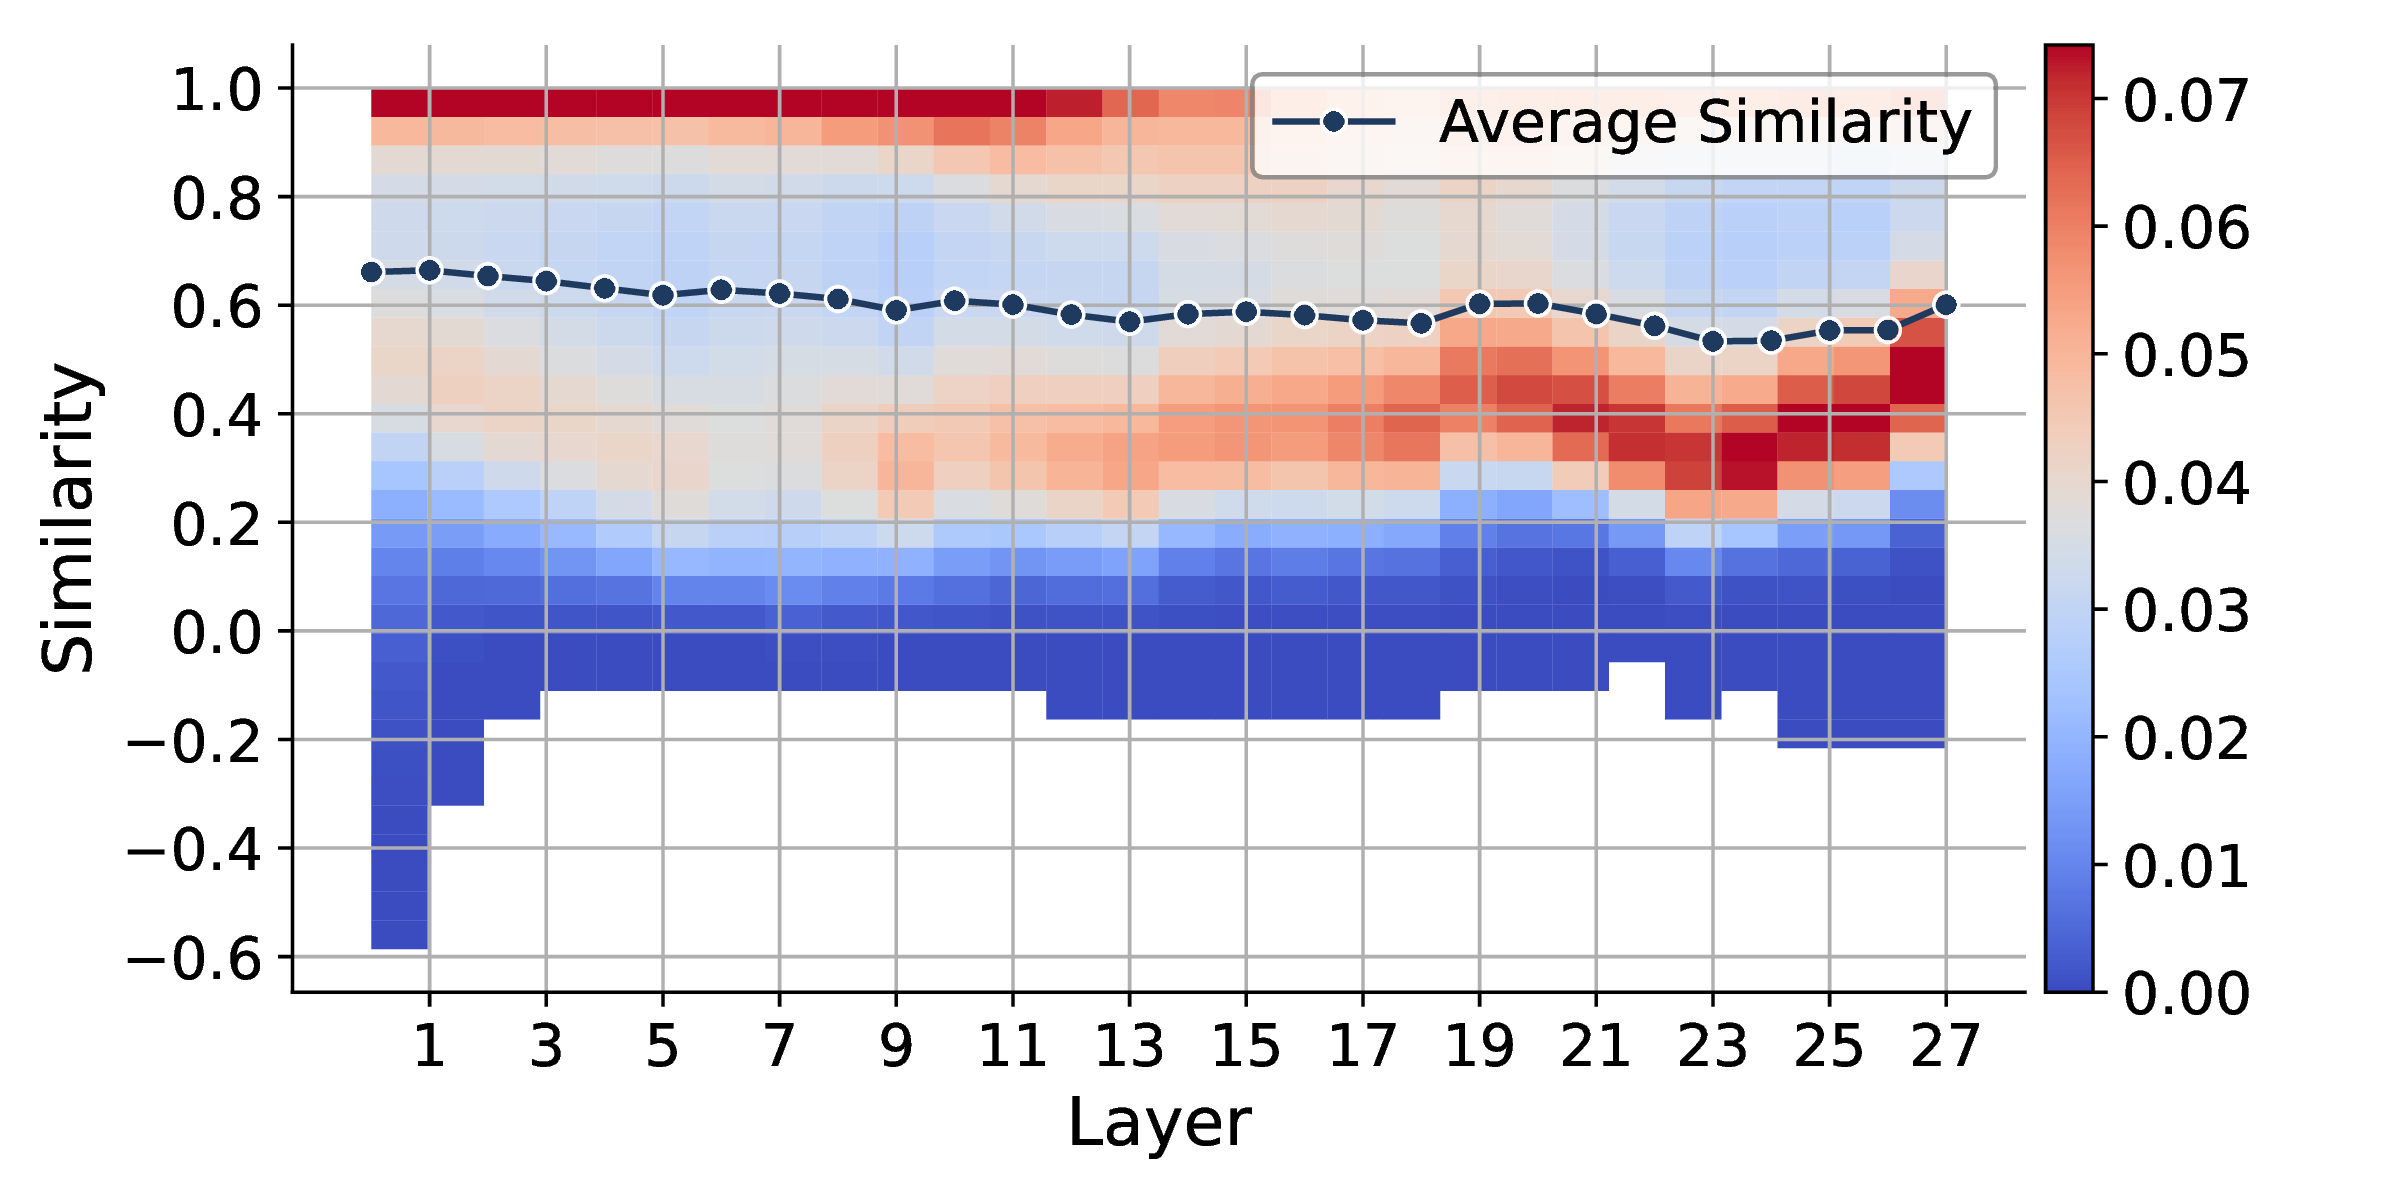
Token similarity distribution condenses as layers deepen
Design Choice: Apply merging at shallow layers
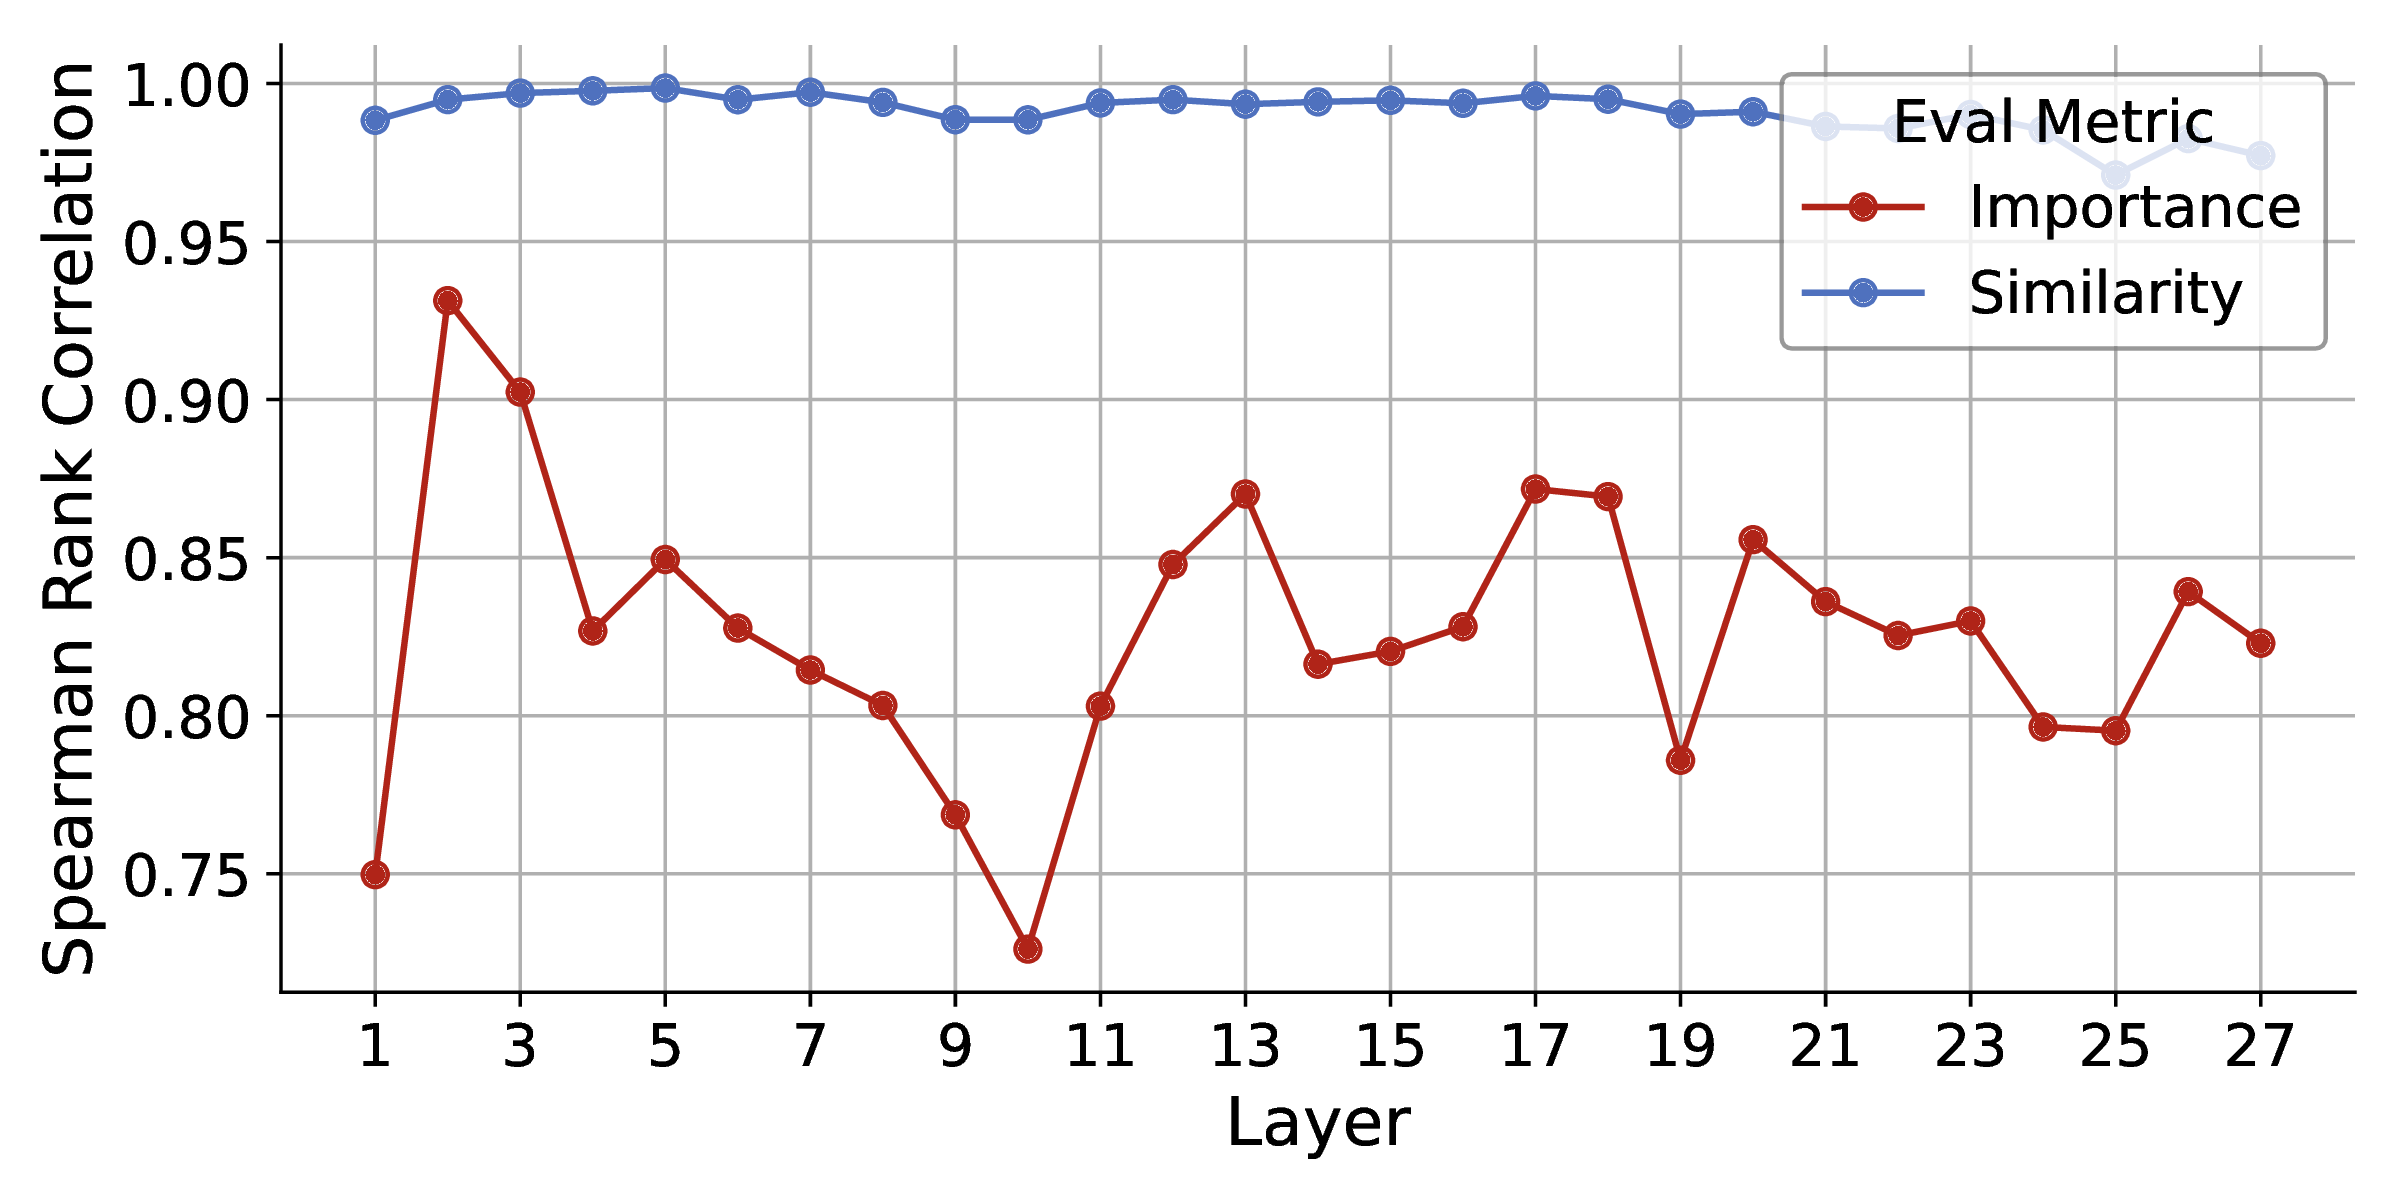
High similarity ranking consistency across layers
Design Choice: Cascaded merging strategy
Interactive Examples
The original page interaction is preserved: compare dense inference with FrameFusion as the token counts and response timing change.
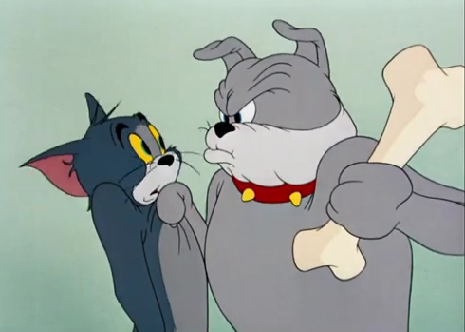
Q: Which animal hit the cat? Answer it simply.
Q: How many main characters are there in the video?
Q: What animal saves the monkey? Answer it simply.
Experiments
FrameFusion reduces video tokens aggressively while preserving benchmark accuracy and improving latency.
Watch FrameFusion in action: See how our method efficiently processes video content while maintaining visual quality.
Performance comparison across models, methods, and benchmarks at 30% token budget
| Model | Size | Method | VideoNIAH | NExT-QA | VideoMME | EgoSchema | MVBench | Average |
|---|
FrameFusion runtime performance with different token budgets and frame counts. Select a model and cost level to see the comparison with the original model.
FrameFusion achieves 1.6-3.6x end-to-end speedup, scaling better with larger models and more frames.
Select a model and cost level to see speedup statistics.
Interactive Demo
Compare the original video frames with FrameFusion-processed frames. Use the slider to see how our method maintains visual quality while reducing tokens.
Original Frame
(256 tokens)
After FrameFusion
(77 tokens)
Token reduction maintains semantic understanding while significantly reducing computation.
Citation
@article{fu2025framefusion,
title = {FrameFusion: Combining Similarity and Importance for Video Token Reduction on Large Vision Language Models},
author = {Fu, Tianyu and Liu, Tengxuan and Han, Qinghao and Dai, Guohao and Yan, Shengen and Yang, Huazhong and Ning, Xuefei and Wang, Yu},
journal = {arXiv preprint arXiv:2501.01986},
year = {2025}
}